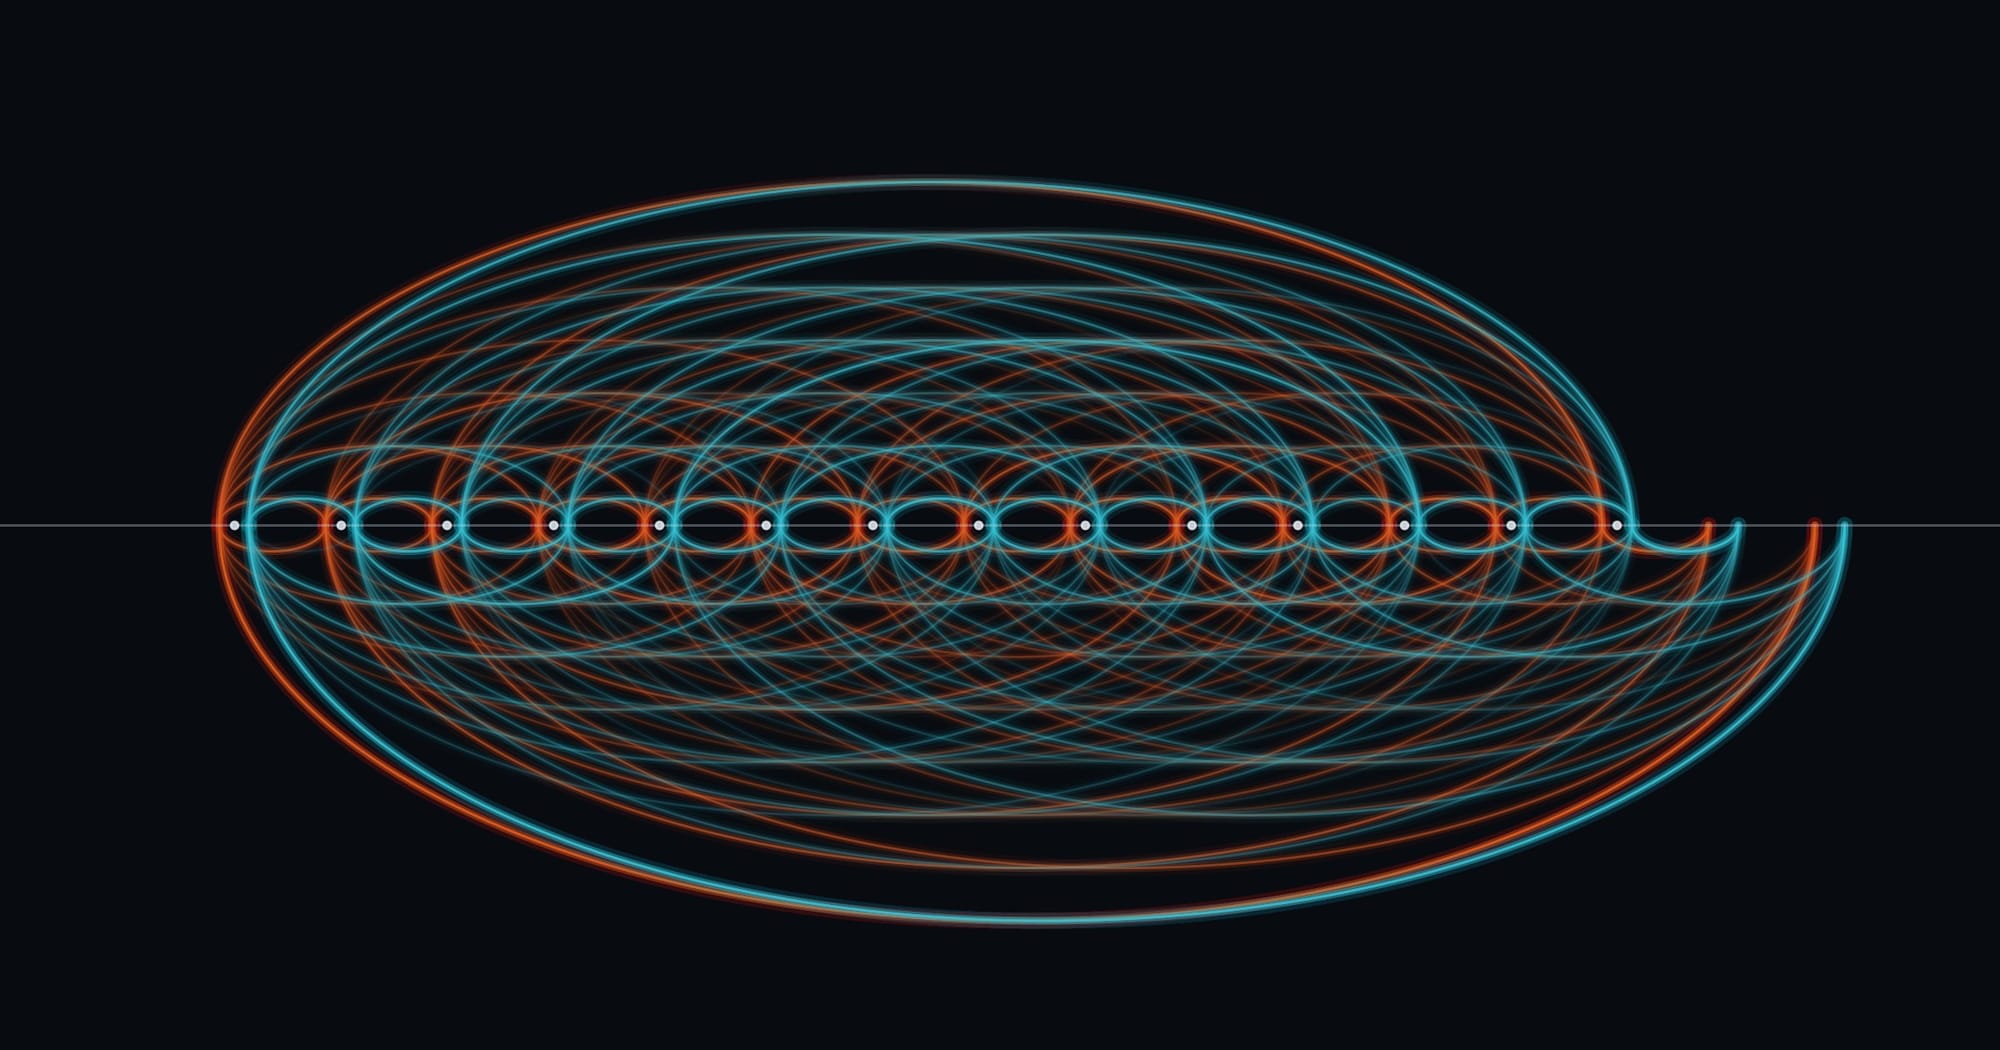
Two rivers, one road: Rust and OxCaml race to count meanders
Recently we counted Arnold's meanders, the ways a river can cross a straight road n times, with programs proved correct in Lean. The verified transfer matrix reaches 32 crossings in a minute and a half. Proofs make every number certain; they do not make the program fast. So we asked a second question: if we keep exactly the machine that Lean proved correct, how far can we go with the fastest code we can write? And what if two very different languages try?
One program is in Rust. The other is in OxCaml, Jane Street's branch of OCaml, which adds modes, unboxed types and data-race-free parallelism to the language. Both run on all cores, both check every count against the values Lean certified and against the OEIS, and both reached far beyond 32. Along the way OxCaml took the lead, we explained why, and the explanation turned out to be half wrong. Here is the race.
The shared machine
The transfer matrix scans the road from west to east. At each bridge the river either opens a new arc or closes one, above the road and below it, and the state records how the open arcs are connected by pieces of river further west. Equal states are merged and their counts added. Lean stores a state as two stacks of references.
The fast programs store it as one 64-bit word. Read the open arcs along a vertical cut, top to bottom: the pieces of river west of the cut never cross, so they pair up the arcs like brackets. A state is a bracket word, with one extra marker for the arc that leads to the river's east end, plus the number of arcs above the road. One bit per bracket fits every state up to 52 crossings.
The parallel design is the same in both languages. Each layer of states is split into 4,096 hash shards, each a table behind its own lock. Workers claim source shards, compute successors, batch them by target shard, and add a full batch under that shard's lock. Counts beyond 64 bits come from two sweeps, modulo 2^64 (2^63 in OCaml) and modulo the prime 2^61 − 1, joined by the Chinese remainder theorem.
Rust: the memory wall
The first Rust version used 128-bit keys and counted n = 43 in 15 seconds on a 10-core laptop, using 8.5 GB. Memory, not time, was the wall: each extra crossing multiplies the largest layer by about 1.55. Counts kept modulo 64-bit numbers and the 64-bit key halved the bytes per state. Packing and unpacking that key, letter by letter, first cost about 30 percent more time; bit interleaving, the trick behind Morton codes, made both constant-time.
A surprise came on the workstation, an 18-core Xeon with 128 GB. There small values ran two and a half times slower than on the laptop. Each of 36 threads was allocating 4,096 batch buffers for every layer, half a gigabyte before doing any work. Allocating a buffer on first use made them five times faster.
Then the reach. On the laptop Rust counted 48 crossings: 2,069,504,277,256,274,074,724 meanders, from a largest layer of 872 million states. On the workstation it counted 49 in 516 seconds and 50 in 1,052 seconds: 22,206,891,674,746,169,557,410 meanders, from a layer of 2.25 billion states, using 79 GB. Every value matches the OEIS. Fifty is as far as 128 GB goes.
OxCaml: safety without the cost
OCaml programs usually allocate freely and let the garbage collector clean up. That is fatal at a billion states, and OxCaml's additions are what make the alternative possible:
- Modes. A value marked
locallives on the stack. The inner loop allocates nothing on the heap, so the garbage collector never stops the workers. - Capsules. Each shard is a capsule: shared mutable data that can only be reached through its mutex. The compiler checks this. When the first version passed a worker's mutable buffer into the lock's callback, the compiler rejected it: inside a
portablefunction, the buffer iscontended, and contended data cannot be read. Data races are ruled out at compile time, not by care. - Unboxed types. States are immediate integers, successors come back as an unboxed tuple in registers, and the tables are flat arrays the garbage collector never scans.
- A barrier, avoided safely. On ARM, OCaml 5 places a memory barrier before every store into mutable memory, about 10 nanoseconds each in a tight loop. Stores of unboxed floats skip it. Since the modes already prove the program race-free, the tables keep each integer's raw bits in a float slot. No floating-point arithmetic touches them, and one instruction moves the bits each way. That alone made a single-threaded run 30% faster.
OxCaml takes the lead
The first timed comparison on the Xeon, all 36 threads, put OxCaml clearly ahead:
| n | Rust | OxCaml |
|---|---|---|
| 40 | 3.3 s | 2.3 s |
| 44 | 30 s | 25 s |
| 46 | 79 s, 13.6 GB | 62 s, 22.9 GB |
OxCaml was 15 to 30 percent faster and used more memory. On a single thread the two tied at about 20 seconds. That tie looked like the key fact: the languages do the same work at the same speed per state, so the difference had to be in how the parallel sweeps behave.
There was one design difference. Rust grows each shard's table on demand, by half when it is 80 percent full, rehashing while it holds the shard's lock. OxCaml predicts each layer's size from the growth of the previous layers and allocates every table once. Our first explanation: Rust's rehashing under locks makes threads wait on each other, so it scales worse.
Rust catches up
Explanations are cheap; experiments are better. We gave Rust a --presize option that adopts OxCaml's sizing rule exactly, and ran the three programs interleaved on the same idle machine:
| n | Rust | Rust, pre-sized | OxCaml |
|---|---|---|---|
| 40 | 3.6 s | 2.9 s | 2.2 s |
| 42 | 6.1 s | 5.3 s | 5.3 s |
| 44 | 29.9 s | 22.1 s | 25.4 s |
| 46 | 79.8 s, 12.6 GiB | 57.3 s, 17.0 GiB | 64.7 s, 20.5 GiB |
| threads (n = 40) | 1 | 4 | 9 | 18 | 36 |
|---|---|---|---|---|---|
| Rust | 21.3 s | 6.1 s | 3.5 s | 3.0 s | 3.3 s |
| Rust, pre-sized | 17.0 s | 4.8 s | 2.8 s | 2.4 s | 2.9 s |
| OxCaml | 20.4 s | 5.6 s | 2.8 s | 2.2 s | 2.3 s |
Pre-sizing made Rust 20 to 28 percent faster at every thread count, including one. That refutes our explanation: a single thread waits on no locks. The cost was the rehashing itself, every state moved several times as its table grew. And the single-thread tie had been a coincidence. With the same tables, Rust's per-state work is about 20 percent faster than OxCaml's; the rehashing had hidden that, and OxCaml's better tables had made up the difference.
With the same tables, Rust is the fastest program from 44 crossings up and on a single thread. OxCaml keeps the lead for small layers on many threads, most likely because it keeps one pool of workers and their buffers for the whole run, while Rust starts its threads and allocates their buffers again for every layer. That fixed cost matters most when a layer takes milliseconds.
Memory tells the same story in reverse. Pre-sized tables are allocated at full size while the previous layer is still draining, so pre-sized Rust needs a third more memory. OxCaml needs more still, because its freed tables go back to the system only after a major garbage collection, while Rust frees them at once. Rust grows on demand by default, because memory is what limits how far it can count.
What we learned
- The languages were not the difference. A design choice was. Ported across, it moved the lead to the other program.
- Measure before explaining. Our first explanation sounded right and was wrong about the mechanism. One controlled experiment settled it.
- OxCaml delivers Rust-like control with checked safety. With the same design it comes within 13 to 20 percent of tuned Rust and beats it on small layers, with data races ruled out by the compiler. It also found the better table design first.
- Correctness is the fixed point. Both programs run the machine whose correctness Lean proves, and every count is checked against the certified values and the published sequence. Speed is the only thing that varied.
The code, the benchmark harness and every raw result are in the repository: github.com/querygraph/meander, with the programs in rust/ and oxcaml/. The paper, Counting Arnold's Meanders with Verified Algorithms, now describes all the implementations and these benchmarks, and the first post tells how the counting began.
The programs, the experiments and this post were developed with Claude Code.
published with omnighost · Git ebd865206f87 · SHA-256 30887ce8da0616db3ce26fee2afb66a8c3d4340845eddd9f078bec586cfce86a